DeepSeek V4.1-Flash: Faster AI, Lower Costs & More Efficiency
-
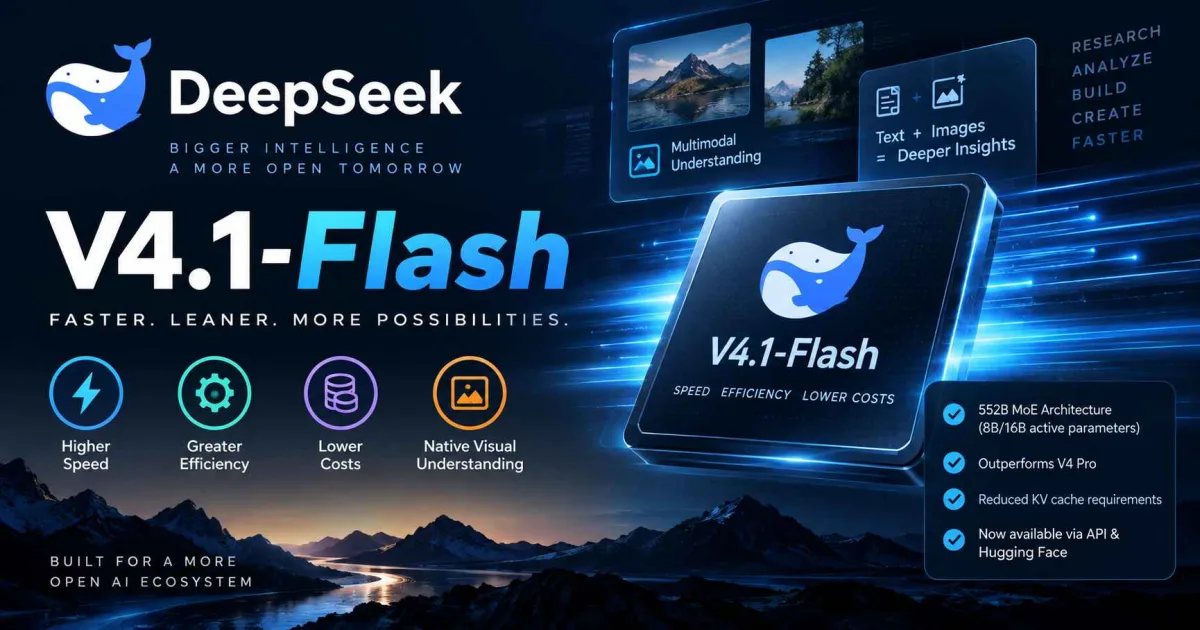
The new model is the smallest in DeepSeek’s V4.1 architecture family and supports native visual understanding.
-
DeepSeek says V4.1-Flash outperforms V4 Pro across performance, speed, cost, and total runtime.
-
The company has lowered API prices and plans to route V4 Pro requests to the new model from Sep 14.
Sep 10, 2026 - Chinese AI company DeepSeek has released V4.1-Flash, a new model built around a more efficient architecture aimed at improving inference speed, throughput, and operating costs. The company describes it as the smallest model in its new V4 architecture family and says it includes native multimodal visual understanding.
The model uses a 552-billion-parameter mixture-of-experts architecture, but only a portion of those parameters are activated during processing. DeepSeek says 8 billion parameters are active for input and 16 billion for output, allowing the system to handle workloads with lower computational requirements than a conventional model of the same overall size.
DeepSeek has also reduced the amount of money required for its key-value cache, a component used to retain information during model processing. The company says V4.1-Flash requires one-quarter of the high-bandwidth memory and one-eighth of the SSD storage used for the KV cache in its previous generation. The efficiency improvements are particularly relevant to AI agents, where long-running tasks can generate substantial inference and memory costs. DeepSeek said its testing showed V4.1-Flash ahead of V4 Pro across performance, cost, speed, and total runtime.
V4.1-Flash is now available through the DeepSeek API with native multimodal support. Developers can access the model using the deepseek-flash model name, while the older V4 Flash and V4 Flash Vision Experimental endpoints have been retired and temporarily routed to the new model for compatibility.
DeepSeek has also reduced API prices for the new model. The company said its peak and off-peak pricing system will remain in place, with off-peak rates set at half the peak rates. The revised pricing took effect on Sep 10.
The company is also phasing out V4 Pro. From 12:00 PM Beijing time on Sep 14, requests sent to the deepseek-v4-pro endpoint will be routed to V4.1-Flash and charged at the newer model’s rates until DeepSeek releases V4.1-Pro
DeepSeek said it plans to work with the open-source community on inference support and expand deployment options for the model. The company has also released V4.1-Flash through Hugging Face. The release comes as DeepSeek prepares for a potential listing on Shanghai’s STAR Market.
Source:
https://api-docs.deepseek.com/updates/
https://www.deepseek.com/en/news/deepseek-v4-1-flash/
https://www.reuters.com/world/asia-pacific/chinas-deepseek-launches-v41-flash-model-2026-09-10/